Part 2 — Why PoCs stall: Engineering the Enterprise Agentic Stack
Most enterprise AI failures don’t look like spectacular blowups. They look like silence: pilots that never become products. The demo worked. Users were excited. Then Security asked about audit trails. IT asked about identity. Legal asked about data residency. Ops asked about incident response. Finance asked why costs spiked. And the project stalled.
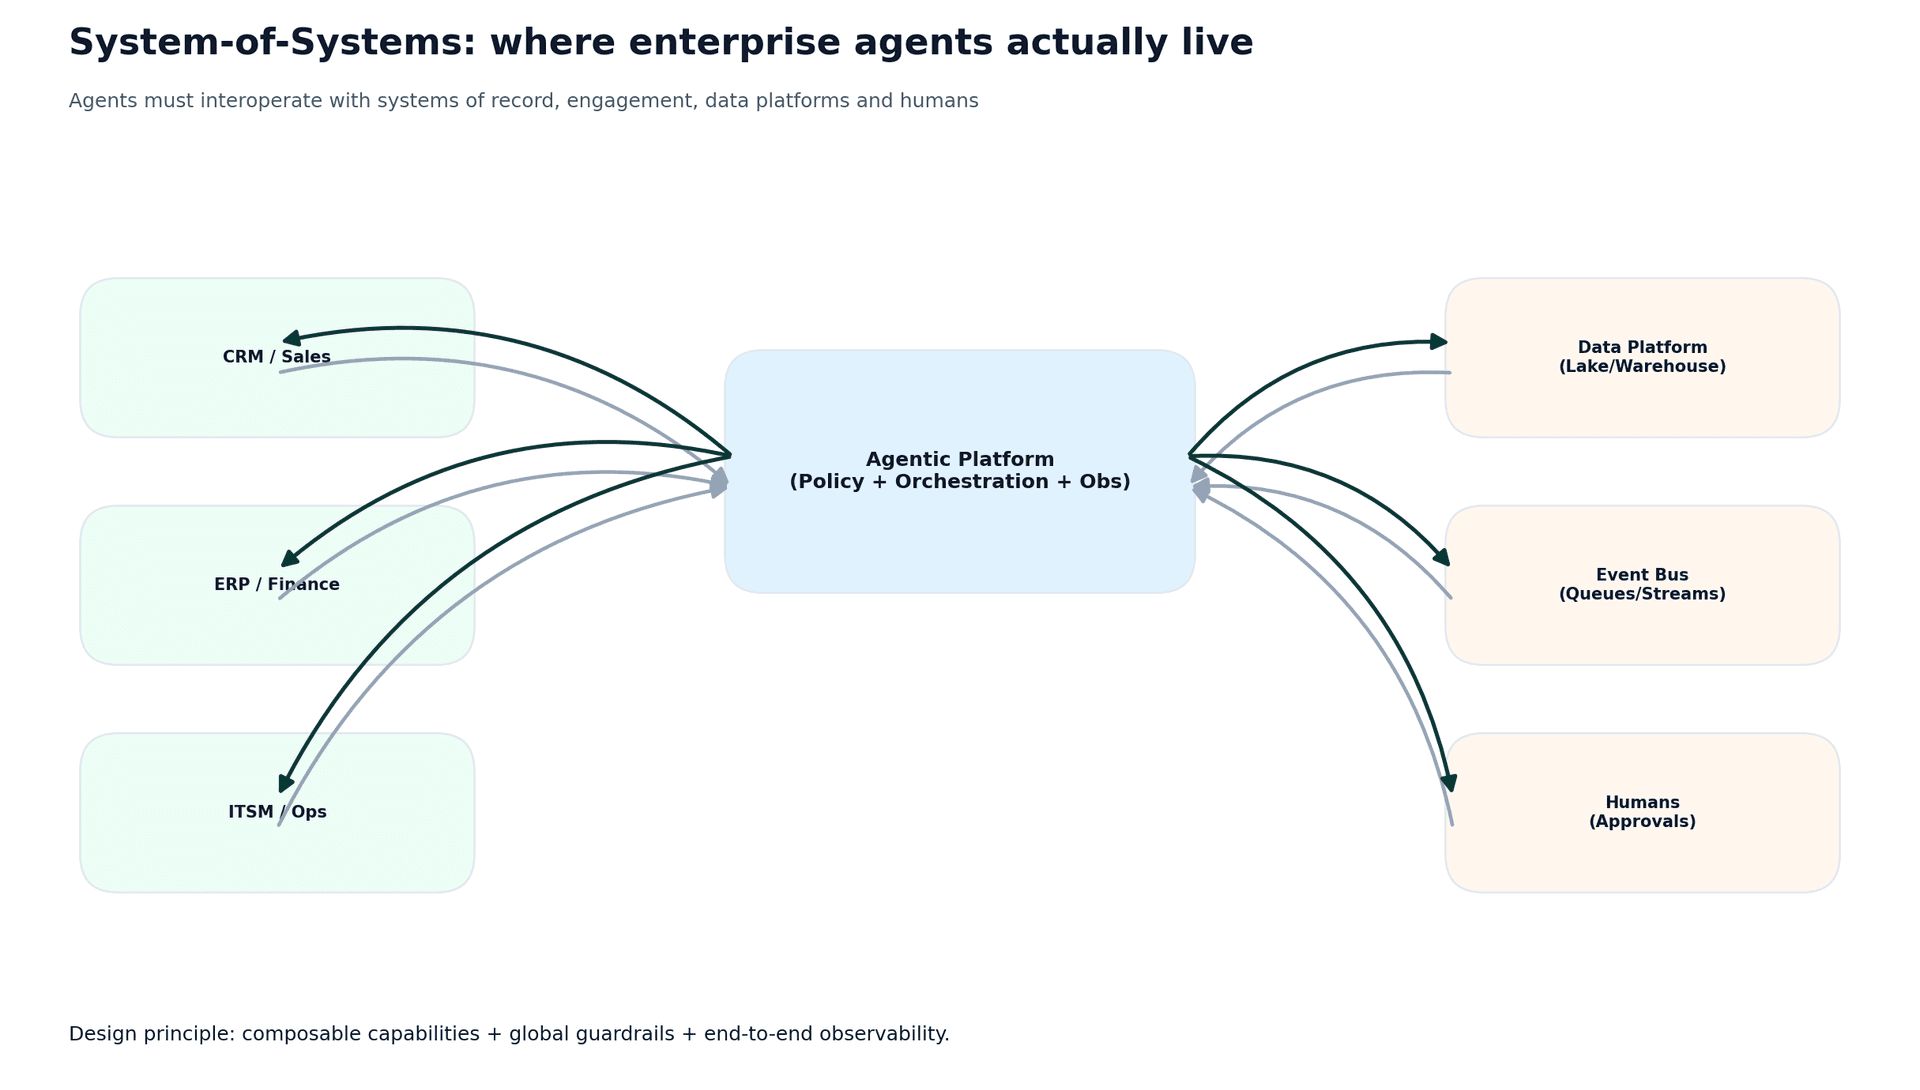
The root causes are predictable—and architectural. Enterprises are system-of-systems. Agents must interoperate with systems of record and engagement, data platforms, and humans. To scale, you must treat agents like governed services, not clever prompts.
Executive summary
The production bottleneck has shifted further away from raw model capability. Integration, workflow redesign, evaluation, identity, governance, and operating ownership now determine whether agents scale.
Managed agent platforms increasingly provide the harness—sessions, state, sandboxing, tools, tracing, evaluation, and identity—but enterprises still own the blast radius, policy, data boundaries, and business accountability.
A practical target architecture now separates enterprise control plane from a replaceable agent runtime/harness, with stable contracts for tools, identity, policy, telemetry, and evals.
Go-live is no longer a one-time checklist. Production agents need continuous observe → evaluate → improve loops, release gates, kill/containment controls, and cost-per-outcome monitoring.
1) Non-functionals are now the moat
In early pilots, teams optimize for a good demo. In production, enterprises optimize for reliability, security, and predictable economics. Futurice’s market framing is blunt: non-functionals now drive architecture decisions more than model benchmarks.
2) Agents live inside a system-of-systems
An enterprise agent is rarely the whole workflow. It is a probabilistic worker embedded inside deterministic systems: CRM cases, ITSM incidents, invoice exceptions, RFP workflows, code repositories, data platforms, and humans. The 2026 platform shift does not remove this system-of-systems reality; it makes the seams more explicit. MCP-style tool interfaces, A2A-style agent interoperability, managed gateways, and agent registries can standardize connectivity, but authorization, transaction semantics, idempotency, data ownership, and accountability remain enterprise design concerns.
3) Failure modes you must engineer for
Most “agent failures” are systems failures. Use this list as a design checklist:
- Indirect prompt injection / agent hijacking → malicious instructions arrive through email, web, files, or tool output (content isolation + policy enforcement + constrained tools + containment).
- Over-privileged agent identities/connectors → excessive blast radius (non-human identity + scoped delegation + just-in-time credentials + least privilege + egress controls).
- Tool timeouts/partial failures (orchestration retries + circuit breakers).
- Non-idempotent actions (duplicate writes) (idempotency keys + safe retry).
- Model, harness, prompt, or tool regressions → silent behavior drift (offline evals + production traces + canary releases + acceptance thresholds + rollback).
- Runaway workflow costs → repeated reasoning, retries, subagents, browser/code sessions, and tool charges (budgets + routing + caching + circuit breakers + cost per successful outcome).
- Compromised MCP/tool or agent supply chain → trusted-looking capability executes unsafe behavior (registry/allowlist + version pinning + provenance + tool-level authorization).
- Long-running state corruption or stale context → agent continues from an invalid assumption (durable checkpoints + explicit state schema + recovery/replay + bounded context).
If you can’t explain how your system behaves under failure, drift, and adversarial inputs, you don’t have an enterprise agent — you have a prototype.
4) Reference target architecture: the Enterprise Agentic Stack
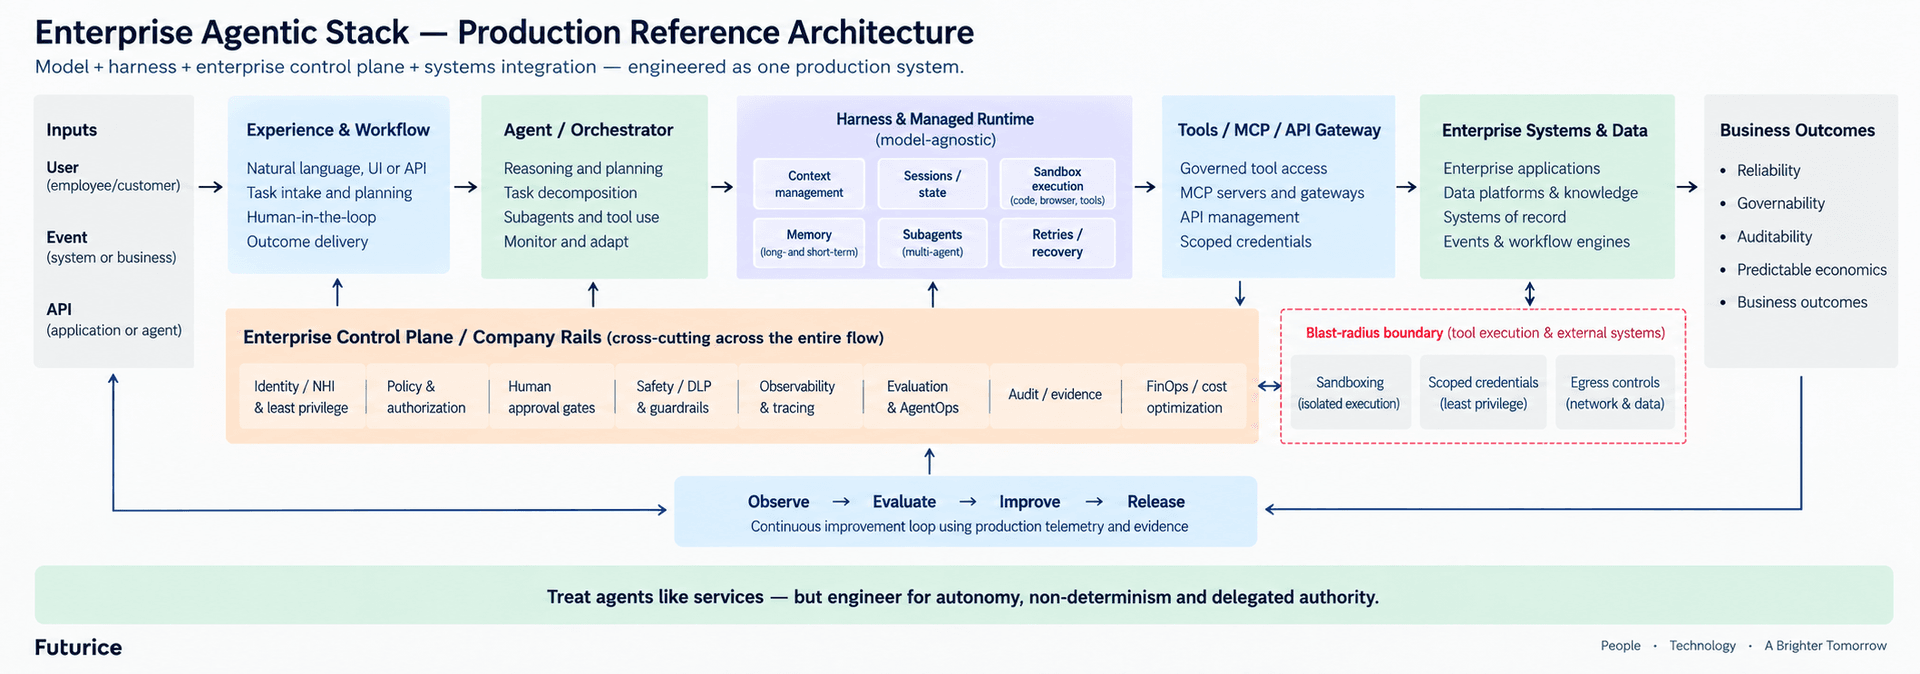
Production programs still converge on layers, but the boundary has changed. Treat the model + harness/runtime as a replaceable execution substrate and put enterprise-specific controls around it: identity/authorization, policy, data boundaries, tool gateway, workflow semantics, telemetry/evals, and FinOps. A managed platform may implement several of those capabilities, but the architecture should keep ownership and evidence explicit. This is the difference between consuming a managed agent service and outsourcing accountability.
Evidence in Action: Futurice AI Reference Cases
When agents are orchestrated as deterministic workflows—synthesizing evidence, correlating events, and acting through controlled tool interfaces—the ROI can be staggering. In the 2026 State of AI Agents report, cybersecurity leader eSentire compressed expert threat analysis from 5 hours to 7 minutes; L’Oréal’s orchestrated conversational analytics reached 99.9% accuracy and scaled to 44,000 monthly users; and Novo Nordisk reduced clinical study documentation production from 10+ weeks to 10 minutes using retrieval‑augmented generation with approved text and case‑specific variables—while meeting regulatory-grade requirements.
The pattern is consistent: not a ‘magic model,’ but strong orchestration + governed retrieval + operational rails that make accuracy, auditability, and scale possible.
Harness engineering: when the rails become the product
Harness engineering has become one of the defining production layers of 2026. A harness is the control and execution machinery around the model: context management, sessions and checkpoints, tool selection, sandboxed execution, subagent coordination, recovery, and telemetry. Anthropic’s Managed Agents made the “brain vs hands” separation explicit in April; OpenAI’s September Agents API now exposes the managed Codex harness for cloud agents that can run for days; Microsoft, Google, and AWS similarly package runtime, tools, memory, identity, observability, and optimization into managed agent platforms. 1
The important shift is not that orchestration disappeared; it moved down into platforms. Horizontal frameworks remain useful when you need custom control, portability, or heterogeneous runtimes, but rebuilding generic session management, sandboxing, retry loops, and tracing is increasingly hard to justify. The enterprise design problem moves upward: workflow semantics, tool contracts, authorization, policy, eval criteria, audit evidence, and integration with systems of record. Those are the parts that encode how your company works. 1,2,3,4,5
So the buy-vs-build decision should be made capability by capability. Buy managed harness primitives when they meet your residency, security, observability, and portability requirements. Build or retain control where the capability expresses business differentiation, regulatory evidence, cross-vendor policy, or irreversible actions. Keep stable seams—MCP/A2A or equivalent tool contracts, identity, telemetry, policy, eval datasets, and workflow state—so a model or runtime change does not become a transformation program.
From PoC to industrialization: The operating loop
The production unit is no longer “an agent deployment”; it is a continuously operated workflow. Industrialization means versioned prompts/models/harnesses, reproducible eval datasets, trace-linked production feedback, staged releases, incident ownership, cost budgets, and a path from failure → evidence → fix → re-evaluation → rollout. Microsoft now describes this as an observe–evaluate–optimize loop, while AWS has added evaluations and unified observability around its runtime primitives. The practical lesson is simple: LLMOps is becoming AgentOps, and the feedback loop is part of the architecture.
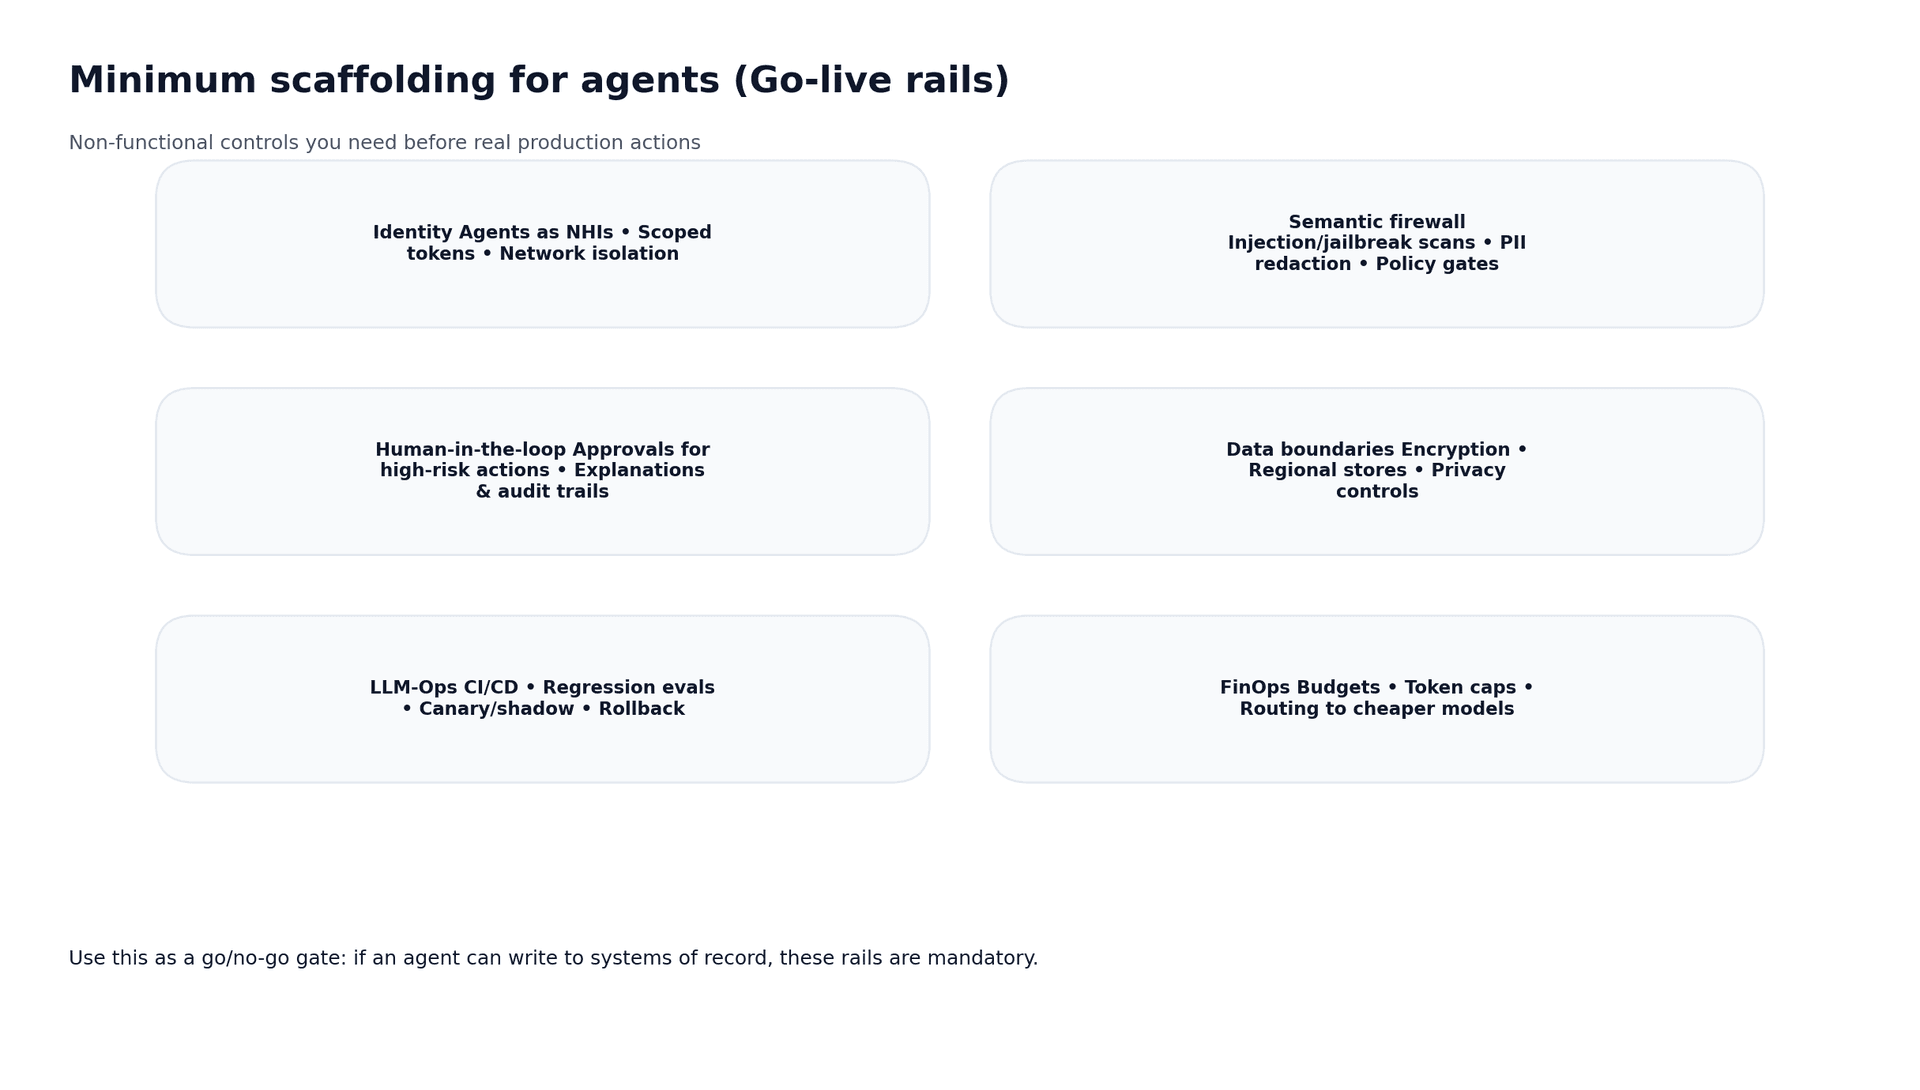
5) Minimum scaffolding for go-live (your gate)
The fastest way to kill trust is still to ship an action agent without rails. But “rails” now need a sharper definition. Enterprise rails are the company-owned control plane that constrains and proves agent behavior across whichever model or managed harness you use: agent identity, scoped authority, policy and data boundaries, containment/egress controls, tool allowlists, human or deterministic approval gates, end-to-end traces, eval/release gates, audit evidence, and cost controls. Treat agents like services—but with explicit blast-radius engineering for probabilistic workers.
6) Use standards as scaffolding (not bureaucracy)
When projects stall, it’s often because stakeholders lack shared language and shared evidence. Standards help you establish both without requiring a multi-year governance program:
- NIST AI RMF for risk vocabulary and lifecycle framing (Govern/Map/Measure/Manage).
- OWASP Top 10 for LLM Apps to translate threats into concrete engineering controls (prompt injection, insecure output handling, tool misuse).
- ISO/IEC 42001 to structure an AI management system (policies, objectives, continuous improvement).
- EU AI Act context for risk-based obligations—especially for regulated deployments in Europe.
What to do next
A target architecture and minimum rails create the conditions for scale, but they don’t automatically produce value.
In the final installment of this series, we will introduce the Futurice AI Maturity Model (FAMM) to help you map your company's context to a pragmatic execution roadmap
References
- The New Stack — “AI Agent Harness Pricing Split” (Apr 2026): thenewstack.io/ai-agent-harness-pricing-split/
- Anthropic Claude Platform release notes — Claude Managed Agents public beta (Apr 8, 2026): platform.claude.com/docs/en/release-notes/overview
- Anthropic Engineering — “Scaling Managed Agents” (Managed Agents / harness design): anthropic.com/engineering/managed-agents
- OpenAI — “The next evolution of the Agents SDK” (model-native harness + native sandbox execution) (Apr 2026): openai.com/index/the-next-evolution-of-the-agents-sdk/
- Google Cloud — Vertex AI Agent Engine overview + pricing (sessions/memory/code execution): docs.cloud.google.com/agent-builder/agent-engine/overview ; cloud.google.com/vertex-ai/pricing
- Microsoft — Foundry Agent Service pricing / hosted agents & Code Interpreter sessions (Apr 2026): azure.microsoft.com/pricing/details/foundry-agent-service/ ; learn.microsoft.com/azure/foundry/agents/
- AWS — Amazon Bedrock AgentCore (agent runtime primitives and secure operation): docs.aws.amazon.com/bedrock-agentcore/ ; aws.amazon.com/bedrock/agentcore/